AI Inference
NVIDIA Dynamo
Scale and serve AI inference—fast.
Overview
The Operating System of AI
Efficiently serving today’s frontier language models often requires resources that exceed the capacity of a single GPU—or even an entire node—making distributed, multi-node deployment essential for AI inference.
NVIDIA Dynamo is an open source, distributed inference-serving framework built to deploy models in multi-node environments at data center scale. It supports open source inference engines—including SGLang, NVIDIA TensorRT™ LLM, and vLLM—and simplifies the complexities of distributed serving by disaggregating inference phases across different GPUs, intelligently routing requests to the appropriate GPU to avoid redundant computation, and extending GPU memory through data caching to cost-effective storage tiers.
NVIDIA NIM™ microservices will include NVIDIA Dynamo capabilities, providing a quick and easy deployment option. NVIDIA Dynamo will also be supported and available with NVIDIA AI Enterprise.
A Closer Look at NVIDIA Dynamo
Low-latency distributed inference framework for scaling reasoning AI models.
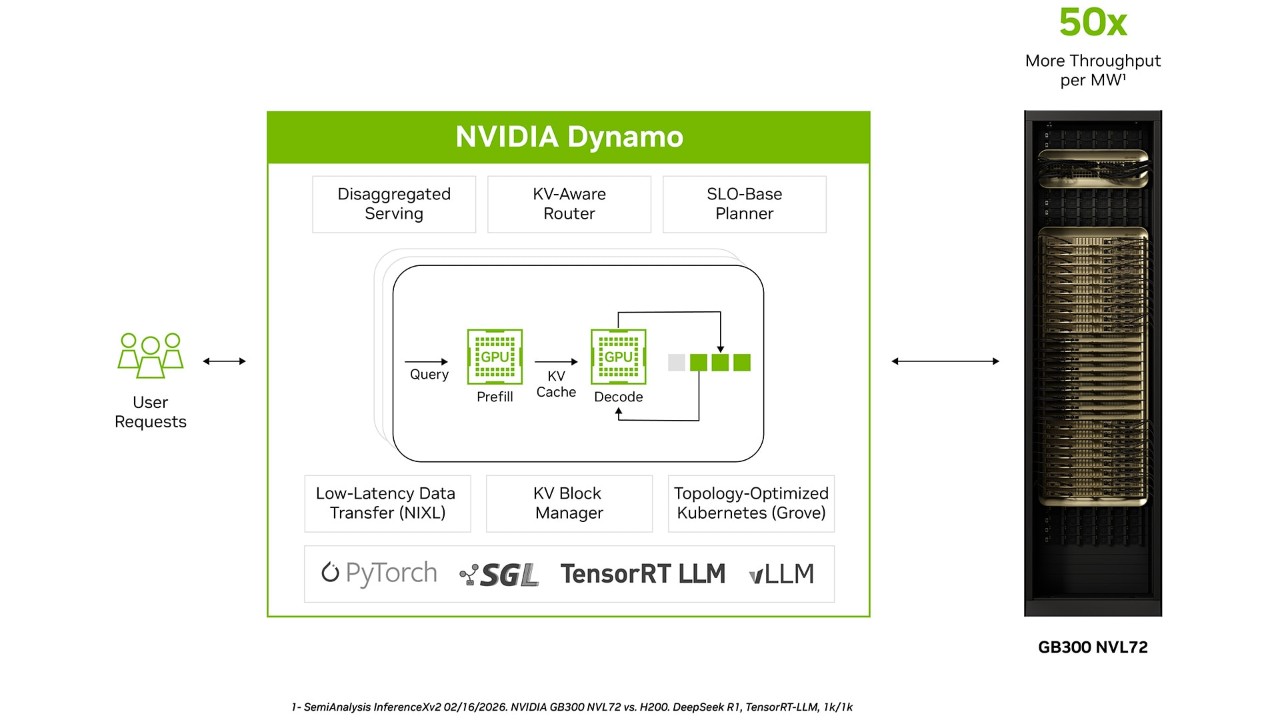
Independent benchmarks show that NVIDIA GB300 NVL72 combined with NVIDIA Dynamo improves Mixture-of-Expert (MoE) model throughput by up to 50x compared to NVIDIA Hopper™-based systems.
The GB300 NVL72 connects 72 GPUs via high-speed NVIDIA NVLink™, enabling low-latency expert communication critical for MoE reasoning models. NVIDIA Dynamo enhances efficiency through disaggregated inference, splitting prefill and decode phases across nodes for independent optimization. Together, GB300 NVL72 and NVIDIA Dynamo form a high-performance stack optimized for large-scale MoE inference.
Features
Explore the Features of NVIDIA Dynamo


Accelerate Distributed Inference
NVIDIA Dynamo is fully open source, giving you complete transparency and flexibility. Deploy NVIDIA Dynamo, contribute to its growth, and seamlessly integrate it into your existing stack.
Check it out on GitHub and join the community!
Benefits
The Benefits of NVIDIA Dynamo

Seamlessly Scale From One GPU to Thousands of GPUs
Streamline and automate GPU cluster setup with prebuilt, easy-to-deploy tools and enable dynamic autoscaling with real-time LLM-specific metrics, avoiding over or under provisioning of GPU resources.

Increase Inference Serving Capacity While Reducing Costs
Leverage advanced LLM inference serving optimizations like disaggregated serving and topology-aware autoscaling to increase the number of inference requests served without compromising user experience.

Future-Proof Your AI Infrastructure and Avoid Costly Migrations
Open and modular design allows you to easily pick and choose the inference-serving components that suit your unique needs, ensuring compatibility with your existing AI stack and avoiding costly migration projects.

Accelerate Time to Deploy New AI Models in Production
NVIDIA Dynamo’s support for all major frameworks—including NVIDIA TensorRT-LLM, vLLM, SGLang, PyTorch, and more—ensures your ability to quickly deploy new generative AI models, regardless of their backend.
Dynamo Ecosystem Partners


Use Cases
Deploying AI with NVIDIA Dynamo
Find out how you can drive innovation with NVIDIA Dynamo.
-
Reasoning Model Serving
-
Kubernetes AI Scaling
-
Deploying AI Agents
-
Code Generation
Serving Reasoning Models
Reasoning models generate more tokens to solve complex problems, increasing inference costs. NVIDIA Dynamo optimizes these models with features like disaggregated serving. This approach separates the prefill and decode computational phases into distinct GPUs, allowing AI inference teams to optimize each phase independently. The result is better resource utilization, more queries served per GPU, and lower inference costs. When combined with the NVIDIA GB200 NVL72, NVIDIA Dynamo boosts compounding performance up to 15x.
Kubernetes AI Scaling
As AI models grow too large to fit on a single node, serving them efficiently becomes a challenge. Distributed inference requires splitting models across multiple nodes, which adds complexity in orchestration, scaling, and communication in Kubernetes-based environments. Ensuring these nodes function as a cohesive unit—especially under dynamic workloads—demands careful management. NVIDIA Dynamo simplifies this by using Grove, which seamlessly handles scheduling, scaling, and serving, so you can focus on deploying AI—not managing infrastructure.

Scalable AI Agents
AI agents generate massive amounts of KV cache as they work with multiple models—LLMs, retrieval systems, and specialized tools—in real time. This KV cache often exceeds the capacity of GPU memory, creating a bottleneck for scaling and performance.
To overcome GPU memory limitations, caching KV data to host memory or external storage extends capacity, enabling AI agents to scale without constraints. NVIDIA Dynamo simplifies this with its KV Cache Manager and integrations with open source tools like LMCache, ensuring efficient cache management and scalable AI agent performance.

Code Generation
Code generation often requires iterative refinement to adjust prompts, clarify requirements, or debug outputs based on the model’s responses. This back-and-forth necessitates context re-computation with each user turn, increasing inference costs. NVIDIA Dynamo optimizes this process by enabling context reuse.
NVIDIA Dynamo’s LLM-aware router intelligently manages KV cache across multi-node GPU clusters. It routes requests based on cache overlap, directing them to GPUs with the highest reuse potential. This minimizes redundant computation and ensures balanced performance in large-scale deployments.

Customer Testimonials
What Are Industry Leaders Saying About NVIDIA Dynamo?

CoreWeave
“As AI moves from experimental pilots to continuous, large-scale production, the underlying infrastructure must be as dynamic as the models it supports. Supporting NVIDIA Dynamo allows us to offer a more seamless, resilient environment for deploying complex AI agents. This foundation provides the durability and high-performance orchestration required to move the industry’s most ambitious agentic workloads into global production.”
Chen Goldberg, EVP of Product & Engineering at CoreWeave

Together AI
“AI Natives require inference that can reliably and efficiently scale with their application. NVIDIA Dynamo 1.0, combined with cutting-edge inference research from Together AI, helps us deliver a high performance stack to offer accelerated, cost-effective inference for large scale production workloads.”
Vipul Ved Prakash, cofounder and CEO of Together AI

“Delivering an intuitive, multimodal AI experience to hundreds of millions of users requires real-time intelligence at global scale. said. As a significant adopter in open source, we’re committed to building scalable AI technologies. With NVIDIA Dynamo optimizing our deployment, we’re expanding the seamless and personalized experiences we deliver, powered by high-performance AI infrastructure.”
Matt Madrigal, CTO of Pinterest
Customer Stories
How Industry Leaders Are Enhancing Model Deployment With the NVIDIA Dynamo Platform


NVIDIA Blackwell Ultra Delivers up to 50x Better Performance and 35x Lower Cost for Agentic AI
Built to accelerate the next generation of agentic AI, NVIDIA Blackwell Ultra delivers breakthrough inference performance with dramatically lower cost. Cloud providers such as Microsoft, CoreWeave, and Oracle Cloud Infrastructure are deploying NVIDIA GB300 NVL72 systems at scale for low-latency and long-context use cases, such as agentic coding and coding assistants.
This is enabled by deep co-design across NVIDIA Blackwell, NVLink™, and NVLink Switch for scale-out; NVFP4 for low-precision accuracy; and NVIDIA Dynamo and TensorRT™ LLM for speed and flexibility—as well as development with community frameworks SGLang, vLLM, and more.

Resources
The Latest in NVIDIA Inference
-
Blogs
-
Sessions
-
Training
-
Videos




Next Steps
Ready to Get Started?
Download on GitHub and join the community!

For Developers
Explore everything you need to start developing with NVIDIA Dynamo, including the latest documentation, tutorials, technical blogs, and more.

Get in Touch
Talk to an NVIDIA product specialist about moving from pilot to production with the security, API stability, and support of NVIDIA AI Enterprise.