Inference
NVIDIA Triton Inference Server
Deploy, run, and scale AI for any application on any platform.
Inference for Every AI Workload
Run inference on trained machine learning or deep learning models from any framework on any processor—GPU, CPU, or other—with NVIDIA Triton™ Inference Server. Part of the NVIDIA AI platform and available with NVIDIA AI Enterprise, Triton Inference Server is open-source software that standardizes AI model deployment and execution across every workload.
The Benefits of Triton Inference Server

Supports All Training and Inference Frameworks
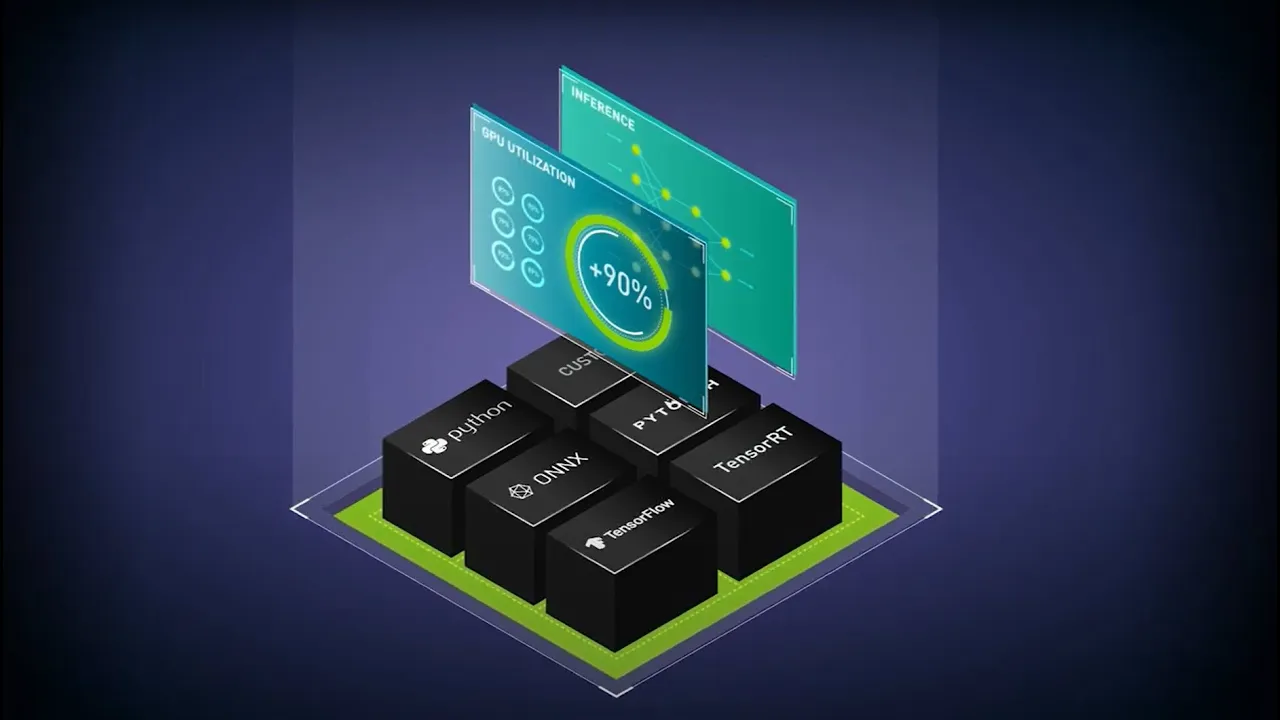
Deploy AI models on any major framework with Triton Inference Server—including TensorFlow, PyTorch, Python, ONNX, NVIDIA® TensorRT™, RAPIDS™ cuML, XGBoost, scikit-learn RandomForest, OpenVINO, custom C++, and more.

High-Performance Inference on Any Platform
Maximize throughput and utilization with dynamic batching, concurrent execution, optimal configuration, and streaming audio and video. Triton Inference Server supports all NVIDIA GPUs, x86 and Arm CPUs, and AWS Inferentia.

Open Source and Designed for DevOps and MLOps
Integrate Triton Inference Server into DevOps and MLOps solutions such as Kubernetes for scaling and Prometheus for monitoring. It can also be used in all major cloud and on-premises AI and MLOps platforms.

Enterprise-Grade Security, Manageability, and API Stability
NVIDIA AI Enterprise, including NVIDIA Triton Inference Server, is a secure, production-ready AI software platform designed to accelerate time to value with support, security, and API stability.
Explore the Features and Tools of NVIDIA Triton Inference Server

Large Language Model Inference
Triton offers low latency and high throughput for large language model (LLM) inferencing. It supports TensorRT-LLM, an open-source library for defining, optimizing, and executing LLMs for inference in production.

Model Ensembles
Triton Model Ensembles allows you to execute AI workloads with multiple models, pipelines, and pre- and postprocessing steps. It allows execution of different parts of the ensemble on CPU or GPU, and supports multiple frameworks inside the ensemble.

NVIDIA PyTriton
PyTriton lets Python developers bring up Triton with a single line of code and use it to serve models, simple processing functions, or entire inference pipelines to accelerate prototyping and testing.

NVIDIA Triton Model Analyzer
Model Analyzer reduces the time needed to find the optimal model deployment configuration - such as batch size, precision, and concurrent execution instances. It helps select the optimal configuration to meet application latency, throughput, and memory requirements.
Leading Adopters Across All Industries
-
Customers
-
Ecosystem Integrations


Get Started With NVIDIA Triton
Use the right tools to deploy, run, and scale AI for any application on any platform.
Begin Developing With Code or Containers
For individuals looking to access Triton’s open-source code and containers for development, there are two options to get started for free:
Try Before You Buy
For enterprises looking to try Triton before purchasing NVIDIA AI Enterprise for production, there are two options to get started for free:
Resources
-
Videos
-
Training
-
Blogs
-
Sessions
-
Customer Stories
-
Community


Next Steps
Ready to Get Started?
Use the right tools to deploy, run, and scale AI for any application on any platform, or explore more development resources.
Get in Touch
Talk to an NVIDIA product specialist about moving from pilot to production with the security, API stability, and support of NVIDIA AI Enterprise.
Get the Latest on NVIDIA Triton Inference Server
Sign up for the latest news, updates, and more from NVIDIA.