
NVIDIA DGX B200
The foundation for your AI factory.
Revolutionary Performance Backed by Evolutionary Innovation
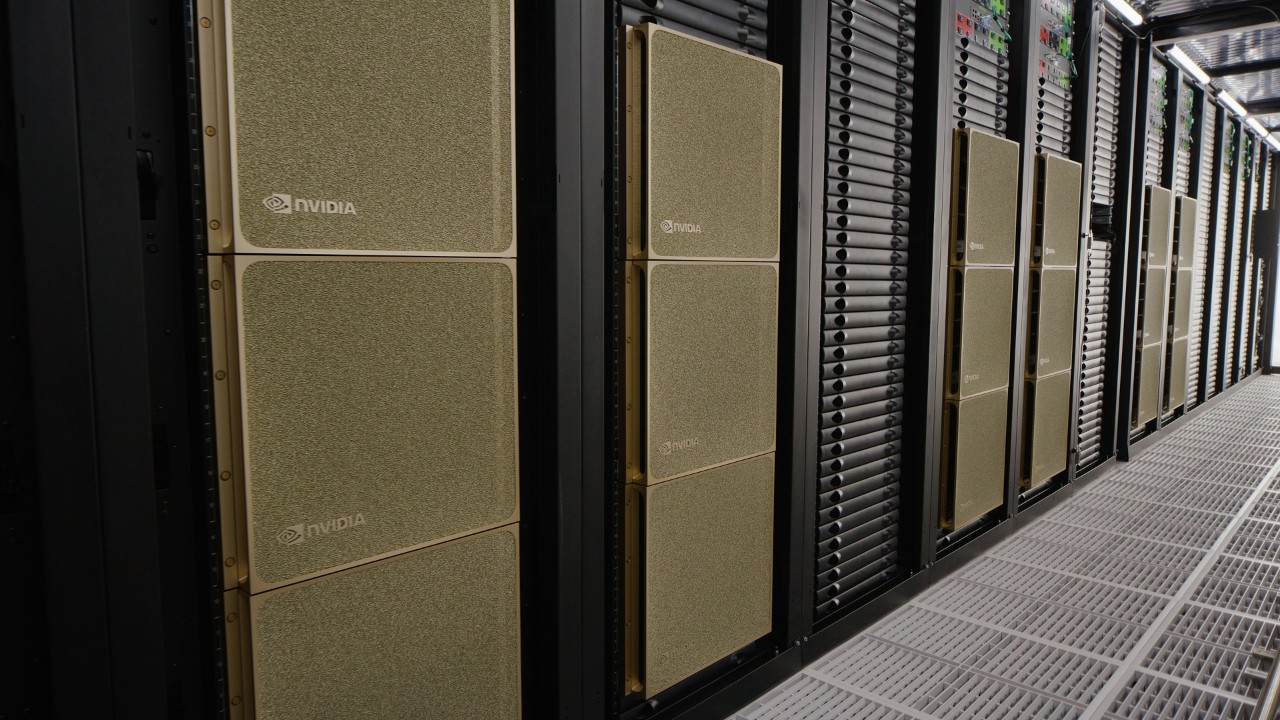
NVIDIA DGX™ B200 is a unified AI platform for develop-to-deploy pipelines for businesses of any size at any stage in their AI journey. Equipped with eight NVIDIA Blackwell GPUs interconnected with fifth-generation NVIDIA® NVLink™, NVIDIA DGX B200 delivers 3X the training performance and 15X the inference performance of previous-generation systems. Leveraging the NVIDIA Blackwell architecture, DGX B200 can handle diverse workloads—including large language models, recommender systems, and chatbots—making it ideal for businesses looking to accelerate their AI transformation.
Benefits
A Unified AI Factory


Performance
Next-Generation Performance Powered by NVIDIA DGX B200
Real Time Large Language Model Inference

Projected performance subject to change. Token-to-token latency (TTL) = 50ms real time, first token latency (FTL) = 5s, input sequence length = 32,768, output sequence length = 1,028, 8x eight-way NVIDIA DGX H100 GPUs air-cooled vs. 1x eight-way NVIDIA DGX B200 air-cooled, per GPU performance comparison.
Supercharged AI Training Performance

Projected performance subject to change. 32,768 GPU scale, 4,096x eight-way NVIDIA DGX H100 air-cooled cluster: 400G IB network, 4,096x 8-way NVIDIA DGX B200 air-cooled cluster: 400G IB network.
Specifications
NVIDIA DGX B200 Specifications
| GPU | 8x NVIDIA Blackwell GPUs |
| GPU Memory | 1,440 GB total, 64 TB/s HBM3e bandwidth |
| Performance | FP4 Tensor Core: 144 PFLOPS | 72 PFLOPS*
FP8 Tensor Core: 72 PFLOPS** |
| NVIDIA NVSwitch | 2x |
| NVIDIA NVLink Bandwidth | 14.4 TB/s aggregate bandwidth |
| System Power Usage | ~14.3 kW max |
| CPU | 2 Intel® Xeon® Platinum 8570 Processors
112 Cores total, 2.1 GHz (Base), 4 GHz (Max Boost) |
| System Memory | 2 TB, configurable to 4 TB |
| Networking | 4x OSFP ports serving 8x single-port NVIDIA ConnectX-7 VPI
|
| Management Network | 10 Gb/s onboard NIC with RJ45
100 Gb/s dual-port ethernet NIC Host baseboard management controller (BMC) with RJ45 |
| Storage | OS: 2x 1.9 TB NVMe M.2
Internal storage: 8x 3.84 TB NVMe U.2 |
| Software | NVIDIA DGX OS / Ubuntu (Included)
NVIDIA AI Enterprise (Recommended) NVIDIA Mission Control (Recommended) |
| Rack Units (RU) | 10 RU |
| System Dimensions | Height: 17.5 in (444 mm)
Width: 19.0 in (482.2 mm) Length: 35.3 in (897.1 mm) |
| Operating Temperature | 10-35°C (50-90°F) |
| Enterprise Support | Three-year Enterprise Business-Standard Support |
|
*Shown in sparse | dense
|
|
Resources
Delivering AI Factories to Every Enterprise
NVIDIA DGX SuperPOD
NVIDIA DGX SuperPOD is a turnkey AI data center infrastructure solution that delivers uncompromising performance for every user and workload. Configurable with any NVIDIA DGX system, DGX SuperPOD provides leadership-class accelerated infrastructure with scalable performance for the most demanding AI training and inference workloads, with industry-proven results, allowing IT to deliver performance without compromise.

Introducing NVIDIA Mission Control
NVIDIA Mission Control streamlines AI factory operations, from workloads to infrastructure, with world-class expertise delivered as software. It powers NVIDIA Blackwell data centers, bringing instant agility for inference and training while providing full-stack intelligence for infrastructure resilience. Every enterprise can run AI with hyperscale efficiency, simplifying and accelerating AI experimentation.
Maximize the Value of the NVIDIA DGX Platform
NVIDIA Enterprise Services provide support, education, and professional services for your NVIDIA DGX infrastructure. With NVIDIA experts available at every step of your AI journey, Enterprise Services can help you get your projects up and running quickly and successfully


Receive an Exclusive Training Offer as an NVIDIA DGX Customer
Learn how to achieve cutting-edge breakthroughs with AI faster with this special technical training offered expressly to NVIDIA DGX customers from the AI experts at NVIDIA’s Deep Learning Institute (DLI).
NVIDIA Blackwell FAQs
NVIDIA Blackwell-powered systems deliver AI inference at $0.02 per million tokens on GPT-OSS-120B using NVIDIA TensorRT™-LLM, as verified by SemiAnalysis InferenceX benchmarks (Q1 2026). $0.02 per million tokens on GPT-OSS-120B represents a 5x improvement over Blackwell’s own launch-day costs, driven by continuous software optimization.
The most important metric for AI inference TCO is the cost per token, or the price-performance actually delivered. According to SemiAnalysis InferenceX benchmarks as of April 2026, NVIDIA Blackwell-powered systems deliver inference at approximately $0.02 per million tokens at 55 TPS/user for GPT-OSS-120B using TensorRT-LLM—roughly 4.5x cheaper than NVIDIA Hopper-powered systems at $0.09 per million tokens with vLLM.
Get Started