What Is Synthetic Tabular Data?
Synthetic tabular data is machine-generated structured data that mimics the statistical patterns and relationships found in real-world datasets. This enables AI development, analytics, and secure data sharing without exposing sensitive personal information.
How Does Synthetic Tabular Data Work?
Synthetic tabular data generation starts by profiling a source dataset to understand feature distributions, inter-column correlations, and the underlying relationships between variables. Generation models then produce new records that maintain these statistical properties without reproducing any actual source data.
Common generation approaches include deep generative models (such as GANs, VAEs, and diffusion-based architectures), constraint-driven rule engines, and statistical sampling methods. These techniques capture real-world characteristics—categorical distributions, numeric ranges, temporal patterns, and rare-event frequencies—while outputting a structurally equivalent table where rows represent observations and columns represent features.
Evaluation ensures the synthetic dataset is representative. This includes distribution comparison, correlation preservation, machine learning (ML) performance testing, and privacy checks, such as memorization resistance. The goal is high-utility synthetic data that behaves like a real dataset while guaranteeing privacy, as there is no personally identifiable information.
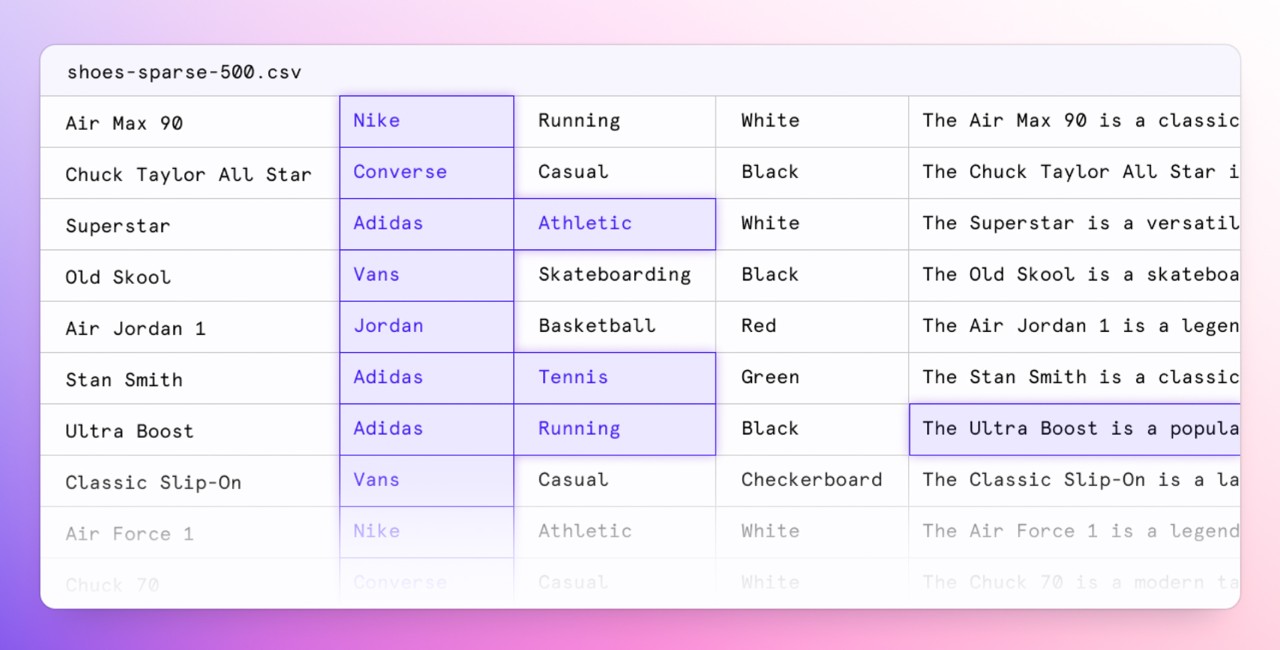
Figure 1: Tabular data organized in rows and columns with fields—demonstrating how structured tables store observations and their attributes for easy analysis.
Generation techniques typically operate column-by-column while preserving cross-feature dependencies to ensure realistic variable interactions. Constraint-based methods enforce domain logic—such as valid value ranges, required field combinations, or business rules—during the generation process.
Hybrid approaches combine learned distributions with explicit constraints, enabling teams to recreate natural variability while maintaining data validity. Modern platforms support dynamic dataset configuration, letting users define custom distributions, scenario parameters, or regional variations. Bias and fairness evaluation should be integrated throughout—synthetic data can perpetuate or amplify skewed patterns from source data if not carefully monitored.

Quick Links
Applications and Use Cases of Synthetic Tabular Data
Synthetic tabular data is used across industries where real data is sensitive, heavily regulated, or difficult to access. Organizations rely on synthetic data for training machine learning models, validating analytics pipelines, accelerating development, and enabling compliant data sharing with partners.
Synthetic tabular data is common in privacy-critical domains like healthcare, finance, security, and telecommunications, as well as in AI development workflows where teams need reproducible, scalable datasets for experimentation.
What Are the Benefits of Synthetic Tabular Data?
Challenges and Solutions
Synthetic tabular data requires balancing realism, privacy, and computational cost. Real-world datasets may contain complex dependencies, rare events, or subtle biases that are difficult to model without careful techniques.
Quick Links

Figure 2. An example of a synthetic data quality and privacy protection report from Gretel platform (2025)
Understanding Tabular Data Workflows
Organizations interested in using tabular synthetic data should begin by defining the target use case, collecting a representative sample of real data, and selecting appropriate generation tools. Evaluate generated data using both utility and privacy metrics before deploying it in production workflows.
Getting started with synthetic tabular data follows a straightforward workflow—from open datasets to custom, production-ready models.
- Start with an NVIDIA Nemotron™ dataset: Choose an open Nemotron dataset aligned with your task—instruction-following, code generation, safety alignment, persona modeling, and more. Browse available datasets at NVIDIA Datasets on Hugging Face.
- Add domain examples and expertise: Create 50–200 examples that reflect your specific use case: your terminology, edge cases, formats, and schemas. These seed examples encode your domain knowledge for scalable synthetic data generation.
- Synthesize high-quality data samples: Use the NVIDIA NeMo™ Data Designer to generate thousands of validated examples. Configure generation models, design dataset columns, preview outputs, and iterate before producing your full dataset.
- Validate before you train: Leverage built-in validation to assess whether synthetic data improves model performance, identify quality issues or biases, and quantify privacy risk—before investing compute in training.
- Fine-tune a Nemotron model: Fine-tune an open Nemotron model on your custom dataset. Go from base model to specialized AI in hours.
- Iterate with real-world feedback: Feed production failures and edge cases back into your dataset pipeline, regenerate, and retrain. Continuous improvement is built into the workflow.
Next Steps
Ready to Get Started?
Synthetic tabular data enables secure, scalable, high-quality datasets for AI development and analytics. Start with open Nemotron datasets and NeMo Data Designer to build production-grade synthetic data pipelines.
Synthetic Data Generation in AI and 3D Workflows
Learn how to generate synthetic data for AI and 3D workflows.
Stay Up to Date on NVIDIA News
Get the latest on synthetic data, generative AI, and NVIDIA's open-source tools for AI development.